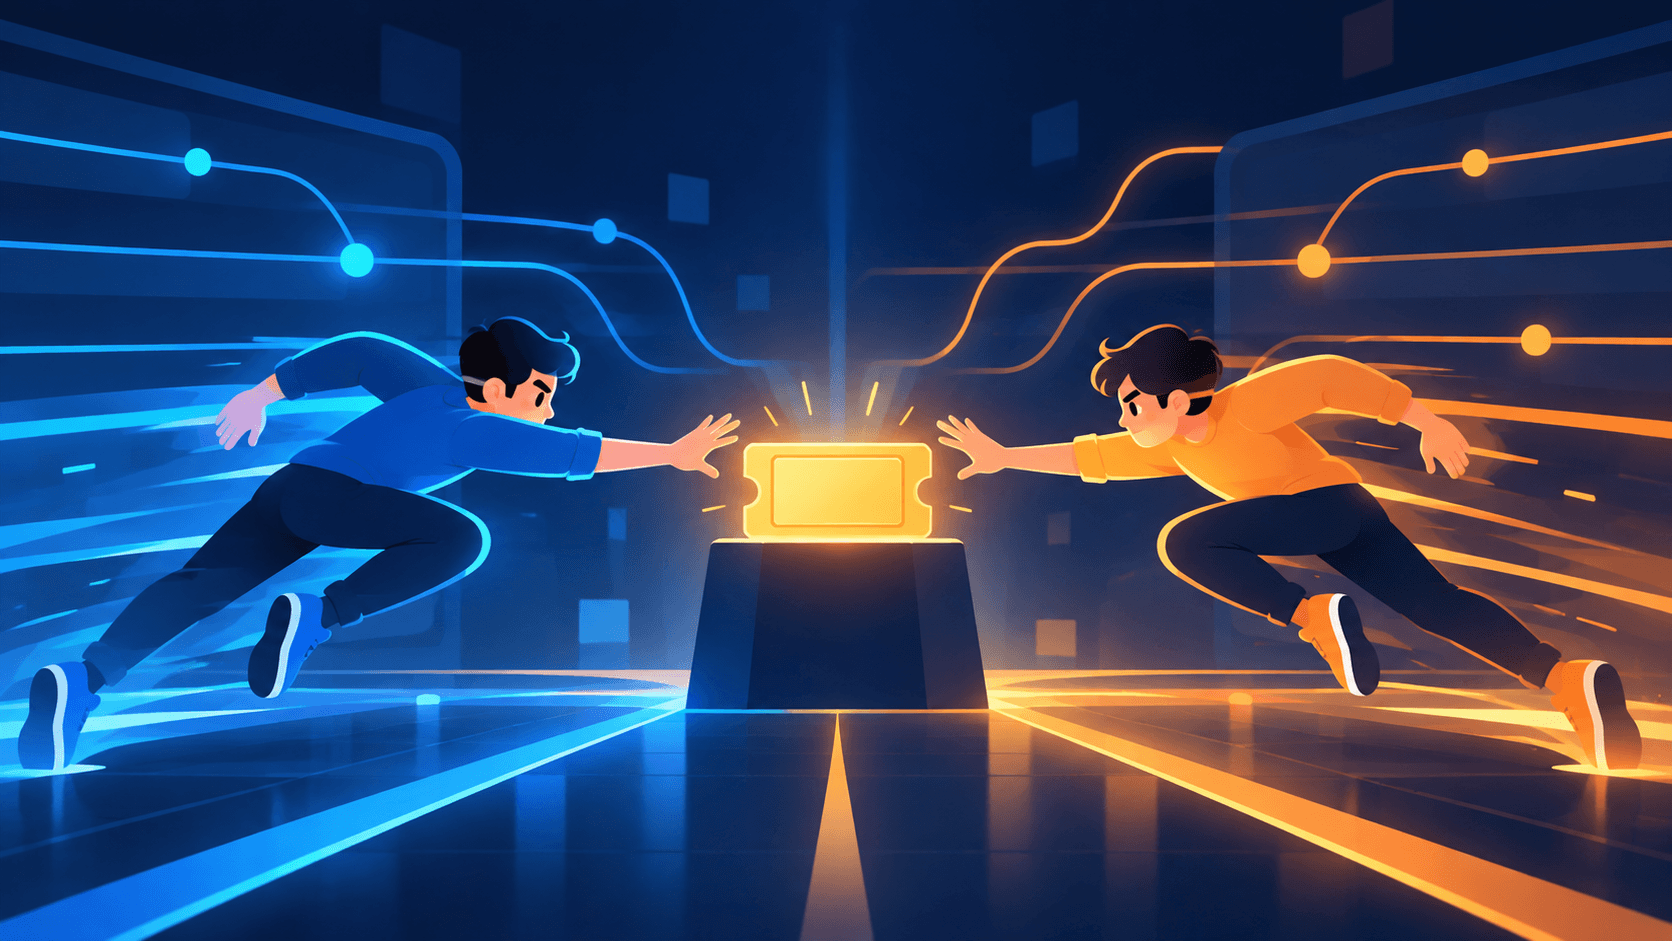
There's a kind of bug that has driven every developer mad at some point: the code runs correctly 99 times, gives the wrong result on the 100th, then works fine again when you rerun it. There's no clear stack trace, you can't reproduce it locally, yet it shows up regularly in production when many users hit the system at once. That's a race condition, one of the hardest bugs to track down in programming.
What Is a Race Condition
A race condition occurs when a program's result depends on the execution order of multiple processes or threads running concurrently, while that order isn't guaranteed. Put simply: two (or more) pieces of code "race" to access and modify a shared resource, and the final result depends on who "finishes" first, something the computer doesn't guarantee will be the same on every run.
The classic example: two threads both run count = count + 1 on a shared counter. It looks like one step, but at the machine level it's three: read the current value, add 1, write it back. If both threads read count = 5 before either writes back, both compute 6 and overwrite each other, leaving 6 instead of 7.
Why They're So Hard to Find
Race conditions depend on timing, the exact moment threads interleave, which is nearly impossible to control or predict. On a developer's machine with little traffic, two threads almost never collide at just the right moment to expose the bug. In production, with hundreds or thousands of concurrent requests, the odds of a collision rise sharply and the bug starts appearing, but not every time.
This makes race conditions almost invisible to normal debugging. Setting a breakpoint to step through the code actually slows that thread down, accidentally making the bug disappear, a phenomenon developers jokingly call a "heisenbug" (a bug that vanishes when you try to observe it).
An Easy-to-Picture Example: The Last Ticket
Imagine a ticketing system with exactly one ticket left. Users A and B click "buy" at almost the same moment. A's request checks "any tickets left?" and gets "1 left". Right after, B's request checks and gets the same answer, because A's request hasn't yet reduced the stock to 0. Result: both A and B get a successful purchase confirmation, while only one ticket actually exists. This is why ticketing, booking, and e-commerce systems are prone to "overselling" during big sales, exactly when the most people buy at once.
How to Detect and Prevent Them
Since race conditions can't always be reproduced, the most effective approach is to design correctly from the start. Common techniques: use locks or mutexes so only one thread accesses a shared resource at a time; use atomic operations (which can't be split or interrupted) for simple operations like incrementing a counter; rely on database transactions to group read-write operations into one unit; and minimize sharing mutable state between threads unless truly necessary.
For testing, stress tests (simulating many concurrent requests) and race detectors such as ThreadSanitizer or Go's race detector are far more useful than rerunning code and hoping the bug shows up. In code review, any code that touches shared resources (global variables, files, database records) across threads or requests deserves extra scrutiny.
Race conditions are a reminder that code which "works" when you test it alone doesn't mean its logic is actually correct. Only when many users and threads touch it at once does the truth come out, and usually at the worst possible moment.